An engraving of a winged classical statue, wings spread wide

Your brand insideYour clients inside AI answers

Beacon connects your live catalogue to ChatGPT, Claude and Gemini. Every week it reports what they said about your products.Beacon connects every client’s catalogue to ChatGPT, Claude and Gemini. Every week it reports what they said, under your name.

The same question, with and without Beacon

A shopper asks. The assistant answers from whatever it read last, or from your own catalogue.A shopper asks. The assistant answers from whatever it read last, or from your client’s own catalogue.

Without Beacon

Answered from memory

ChatGPT

which running shoes should I get for marathon training?

The shopper

A few that come up often are the Adidas Adizero range, New Balance’s FuelCell line and the ASICS Gel-Nimbus.

Nike makes running shoes as well. I don’t have current models, sizes or stock.

Based on four review round-ups, last indexed 9 months ago.

ChatGPT can make mistakes. Check important info.
With Beacon

Prototype

ChatGPT

which running shoes should I get for marathon training?

The shopper

Two Nike road shoes cover most of a marathon block: the Pegasus 41 and the Vomero 18.

Pick one to see what the brand publishes about it.

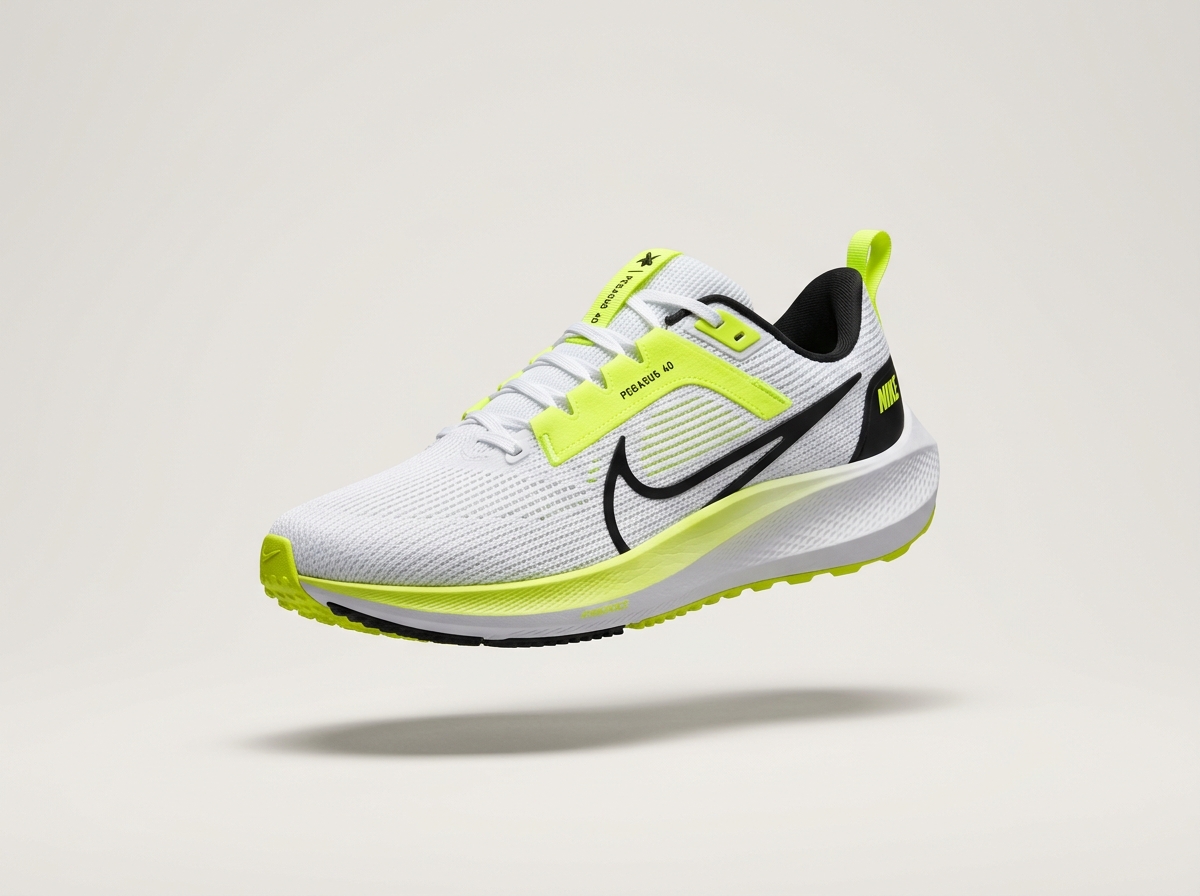
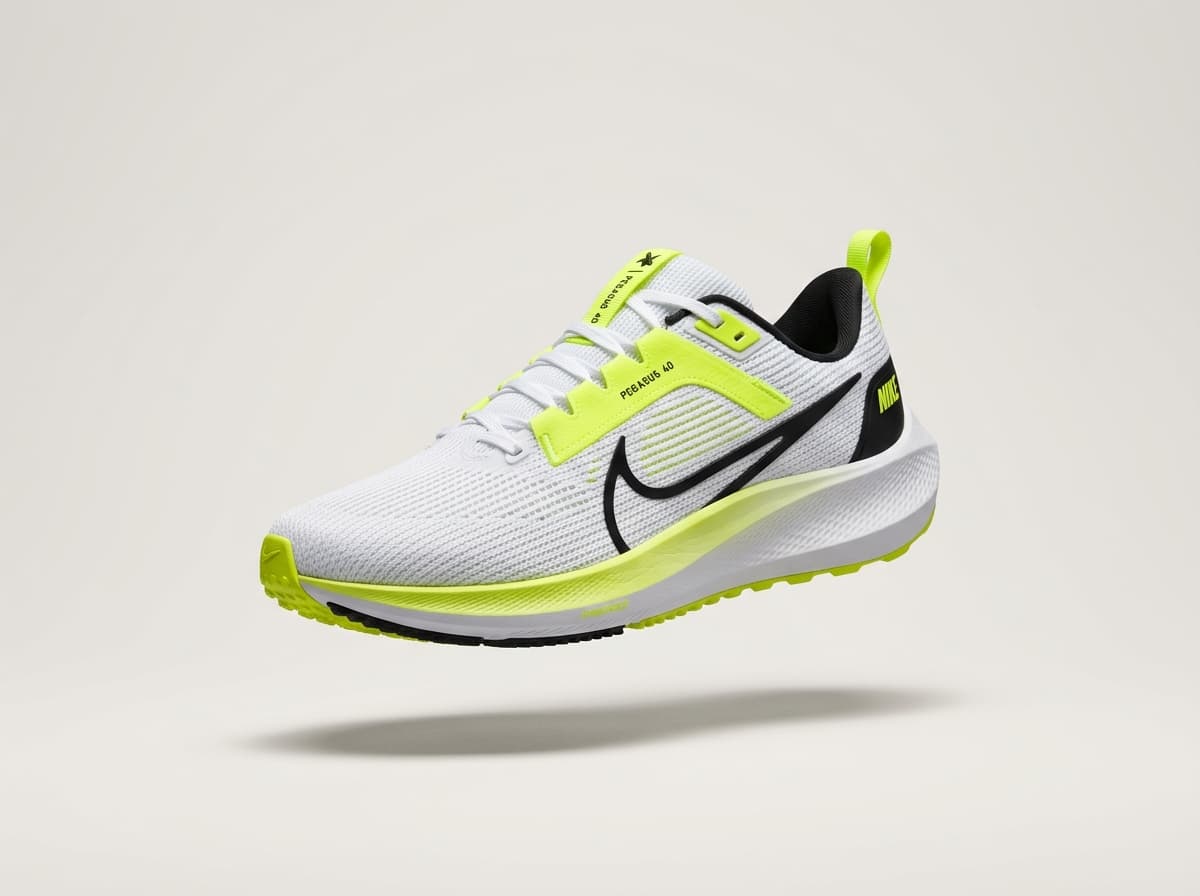
A Nike Pegasus 41 running shoe in white and volt, shot from the side.
Nike Pegasus 41Everyday training
Role
Everyday training
Surface
Road
Source
Brand feed

Two things a shopper can do without leaving the answer.

Answered from the brand catalogue feed.

ChatGPT can make mistakes. Check important info.

The competitor list mirrors one real capture, Aug 2026. The branded answer is a prototype.

Who’s already answering

Booking.com: Travel & accommodation. Answering inside ChatGPT. See the board row.Expedia: Travel & accommodation. Answering inside ChatGPT. See the board row.Zillow: Real estate. Answering inside ChatGPT. See the board row.Spotify: Music & audio. Answering inside ChatGPT. See the board row.Instacart: Grocery & delivery. Answering inside ChatGPT. See the board row.Starbucks: Coffee & QSR. Answering inside ChatGPT. See the board row.Turkish Airlines: Airlines. Answering inside Gemini. See the board row.Burger King: Coffee & QSR. Answering inside Gemini. See the board row.Popeyes: Coffee & QSR. Answering inside Gemini. See the board row.Tim Hortons: Coffee & QSR. Answering inside Gemini. See the board row.Canva: Design & creation. Answering inside ChatGPT. See the board row.Figma: Design & creation. Answering inside ChatGPT. See the board row.Picsart: Design & creation. Answering inside ChatGPT. See the board row.Virgin Atlantic: Airlines. Answering inside ChatGPT. See the board row.Ryanair: Airlines. Answering inside Claude. See the board row.trivago: Travel & accommodation. Answering inside Claude. See the board row.Viator: Tours & experiences. Answering inside Claude. See the board row.Tubi: Streaming & video. Answering inside ChatGPT. See the board row.Shazam: Music & audio. Answering inside ChatGPT. See the board row.Fever: Events & ticketing. Answering inside Claude. See the board row.Ticketmaster: Events & ticketing. Answering inside ChatGPT. See the board row.Domino's India: Coffee & QSR. Answering inside Claude. See the board row.Zomato: Restaurants & delivery. Answering inside Claude. See the board row.Shopee: Marketplaces. Answering inside ChatGPT. See the board row.Etsy: Marketplaces. Answering inside ChatGPT. See the board row.Fresha: Beauty & wellness bookings. Answering inside Claude. See the board row.Checkatrade: Home services. Answering inside Claude. See the board row.TurboTax: Tax & personal finance. Answering inside Claude. See the board row.Uber: Ride hailing. Answering inside ChatGPT and Claude. See the board row.Uber Eats: Restaurants & delivery. Answering inside Claude. See the board row.Tripadvisor: Travel & accommodation. Answering inside Claude. See the board row.Hilton: Travel & accommodation. Answering inside ChatGPT. See the board row.Eurostar: Rail travel. Answering inside ChatGPT. See the board row.Grubhub: Restaurants & delivery. Answering inside ChatGPT. See the board row.Lowe's: DIY & home improvement. Answering inside ChatGPT. See the board row.ASOS: Fashion. Answering inside ChatGPT. See the board row.Prada: Fashion. Answering inside ChatGPT. See the board row.Klarna: Payments & cards. Answering inside ChatGPT. See the board row.Peloton: Fitness. Answering inside ChatGPT. See the board row.AllTrails: Sport & outdoors. Answering inside Claude. See the board row.Taskrabbit: Home services. Answering inside Claude. See the board row.Adobe: Design & creation. Answering inside Claude. See the board row.
42 brands on the board

See the whole board

Be in the answerPut every client in the answer when a shopper asks ChatGPT.

The assistants describe your products from reviews, retailer pages and whatever your competitors published last. Beacon connects them to your own catalogue.The assistants describe your clients from reviews, retailer pages and whatever their competitors published last. Beacon is the stack you run to fix that, client by client, under your own name.

Beacon runs on your product data

Your specs, stock levels and pricing become one feed the assistants read, and it updates when you do.

  1. 01One feed from your own catalogue
  2. 02You approve every word it writes back
  3. 03Maintenance and rebuilds sit with Beacon

One brain, many surfaces

Catalogue, specs, tone, stock and pricing become one source, published over MCP. Every connected surface, from the flagship assistants to the agents your customers run, reads from it.

  1. 01Connect the brain
  2. 02Speak the protocol every surface reads
  3. 03Report what happened
One brain, many surfacesOne structured source of product knowledge publishes over MCP into six surfaces: ChatGPT, Claude, Gemini, Perplexity, Shopee and the agents customers run. Every appearance reports back into the Beacon Console.One brainConsole

Who Beacon is for Agencies, consumer brands, retailers and carmakers.

You connect your product data once, and four different jobs sit on top of it. Pick the one that sounds like yours.A client connects their product data once, and four different jobs sit on top of it. Pick the one that sounds like yours.

Put your clients in the answers under your own name.

A client asks what you are doing about ChatGPT, and wants a number.

  1. 01TodayYou send a deck. Nothing gets built, priced or reported after it.
  2. 02What Beacon doesBeacon builds it, gets it onto the assistants and reports on it. Your name is on all of it.
  3. 03What changesYou keep the client relationship, and the work bills every month.

Evidence

42 brands are already listed inside ChatGPT, Claude and Gemini. Most categories on the Claim Board are still empty.

CanvaRolling outKlarnaRolling outUberRolling outThe Claim Board

Talk to us about a client
A stack of brand guideline books and a colour swatch fan on a coral studio background
Agencies01 / 04

Your share of the answer, what it says, warm or cold, and what it sellsEvery client’s share of the answer, what it says, warm or cold, and what it sells

Beacon puts the questions your shoppers ask to the assistants, records what comes back, and counts what people do next.Beacon puts the questions a client’s shoppers ask to the assistants, records what comes back, and counts what people do next.

  • 01

    The prompts

    The questions shoppers put to the assistants about your category, in the words they use.The questions shoppers put to the assistants about a client’s category, in the words they use.

  • 02

    Share of the answer

    How often the answer names you, and which competitors it names beside you.How often the answer names your client, and which competitors it names beside them.

  • 03

    Warm or cold

    What the answer says about your product, and whether it reads warm or cold.What the answer says about a client’s product, and whether it reads warm or cold.

  • 04

    Right or wrong

    Each answer checked against your own catalogue, so a wrong spec or a discontinued product shows up.Each answer checked against the client’s own catalogue, so a wrong spec or a discontinued product shows up.

  • 05

    What people did

    Find in store, a size guide opened, a booking started, a handoff into your app.Find in store, a size guide opened, a booking started, a handoff into the client’s app.

Nike · Visibility

⌘K
91

Nike

Scaling

Running shoes and training footwear · Nike Run Club · nike.com

Visibility

Where Nike stands inside AI answers · 15 Jul – 13 Aug 2026 · 5 engines live

Share of voice

42.0%

▲+10.4 ptsvs 31.6% baseline · window mean 42.1%

Answer accuracy

99.3%

▲+28.3 ptsup from 71% before the connector

Lead recommendation

39.5%

▲+29 ptsof category answers name it first · from 10.5%

Visibility value

$326,511

media-equivalent · $2.8m since launch

Share of voice

42.0%▲+10.4 pts−0.1 pts vs last month

against a 31.6% pre-program baseline · Month to date across all five answer surfaces, weighted by conversation share

Daily share averaged 42.1% across 15 Jul – 13 Aug 2026 (+0.2 pts on the window before it)

Category share of answers

Pre-program baseline
31.6
30.4
20.6
17.4
Now · 42.0% Nike
42.0
25.6
18.2
14.2
NikeAdidasNew BalanceASICS

Split by engine

Share of voice in the current month, per answer surface

ChatGPT45.3%+13.7 pts
45.3% of conversationsavg position 1.6 · 75.9% mention
Claude38.8%+7.2 pts
14.1% of conversationsavg position 1.8 · 66.4% mention
Gemini40.0%+8.4 pts
21.4% of conversationsavg position 2.1 · 68.6% mention
Perplexity42.9%+11.3 pts
10.9% of conversationsavg position 1.9 · 72.1% mention
AI Overviews33.4%+1.8 pts
8.3% of conversationsavg position 2.6 · 53.1% mention
Weighted by conversation share5 of 5 engines

Share of voice over time

Nike against the category, daily · 15 Jul – 13 Aug 2026

+0.0 pts across the window
  1. 1Marathon build season campaign28 Jul

Answer accuracy

What the engines got right about the products, before and after the connector

71%99.3%on connected queries

Before

71%

Connector added

+28.3 pts

Now

99.3%

Per engine

all five surfaces

ChatGPT
99.5
Claude
99.7
Gemini
99.2
Perplexity
98.9
AI Overviews
98.3
60%baseline 71%100%

Baseline measured on unconnected answers to the same prompt set.

Prompt replaydated 11 Aug 2026

“which running shoe for daily training miles?”

Asked 7,412 times a month across the answer layer · Purchase-consideration intent · product spec

Rendered as answered by ChatGPT1.90s
You

which running shoe for daily training miles?

For daily training miles most runners want a neutral shoe that holds its shape across 40 to 50 miles a week. Fit and outsole wear decide more of the experience than the name on the midsole.

Nike Pegasus 41

Daily trainer

Verified feed
Midsole
ReactX foam
Air units
Zoom Air, heel and forefoot
Offset
10 mm
Use
Daily training

Supplied by the Nike Run Club connector

Adidas and New Balance are the other names that come up on this question.

Check availability near youin-answer CTA → merchant gate

Try them on the surface you actually train on. Fit varies more between models than a spec sheet suggests.

SourcesNike product feednike.comNike Run Club content library

The same prompt, every engine

Where the brand landed in each answer surface

How the category answers

appears in / 5

Adidas5/5

Named alongside Nike in most of the drawn answers for this prompt.

no verified product source
New Balance3/5

Named alongside Nike in most of the drawn answers for this prompt.

no verified product source
ASICS0/5

Not named in any of the drawn answers for this prompt.

Topics × engines

Mention rate: how often the brand appears when the category is asked about. Click a cell for the answers behind it.

TopicQuestions
ChatGPT72%
Claude63%
Gemini66%
Perplexity67%
AI Overviews51%
Mean
Sizing and fit
46.1k
85%
Cushioning and ride
41.3k
87%
Model comparison
33.8k
53%
Support and stability
24.9k
72%
Outsole durability
21.3k
67%
Road, track and trail
19.5k
72%
Price and value
18.7k
37%
Race day shoes
16.5k
61%
Materials and sustainability
13.9k
26%
Care and cleaning
11.3k
77%
Mention rateAbsentWeakPresentStrong

Volume-weighted coverage 68.0% · weakest topic Materials and sustainability at 26%

Position in the answer

Share of category answers by where the brand landed, per month

Named first

39.5%▲+29 pts

from 10.5% in Feb 2026

Left out

14.6%▼−45.9 pts

from 60.5% in Feb 2026

10.5

21.8

29.7

34.7

38.7

39.2

39.5

FebMarAprMayJunJulAugto date
Absent14.6%Mentioned45.9%Lead recommendation39.5%

Sentiment drift

Tone of the answers the brand is named in, per month

Net sentiment

+63.3▲+21.3 pts

from +42.0 in Feb 2026

Negative

5.2%▼−7.1 pts

from 12.3% at program start

54.3

60.0

65.0

67.7

67.9

68.6

68.5

FebMarAprMayJunJulAugto date
Negative5.2%Neutral26.3%Positive68.5%

Citation sources

What the engines cited when they answered about the category

Owned & connected

product feed, brand site and app content

63.2%+34.3 pts

  • Nike product feed (connector)32.4%+22.8 pts
  • nike.com19.6%+3.6 pts
  • Retailer product pages12.8%−5.4 pts
  • Run Club content library11.2%+7.9 pts
  • Review and comparison sites10.4%−8.6 pts
  • Running media and race guides7.6%−3.8 pts
  • Video and creator content4.2%+1.4 pts
  • Forums and community1.8%−1.6 pts

Source mix by engine

Every engine builds its answer from a different diet

ChatGPT53.1% owned · 58.4% cited
Claude53.5% owned · 61.2% cited
Gemini50.7% owned · 49.6% cited
Perplexity51.2% owned · 66.8% cited
AI Overviews53.1% owned · 38.4% cited

All engines · weighted

52.4% owned

Owned52.4%Retail16.5%Editorial16.1%UGC9.9%Other5.1%

Visibility value

Media-equivalent value of the brand's presence in AI answers

$326,511

this month to date · $2,848,614 since program start

The multiplication

104,333 mentions × $3.10

rate benchmarked against paid placement in the same category

FebMarAprMayJunJulAugto date

Contribution by engine

ChatGPT

$177k

50.8k mentions

Claude

$45.5k

13.8k mentions

Gemini

$61.1k

21.6k mentions

Perplexity

$29.9k

11.6k mentions

AI Overviews

$13k

6.5k mentions

Media-equivalent value is a modelled figure, not booked revenue. It is shown so visibility can be compared against the paid budget it displaces. Attributed revenue lives in Actions & Revenue.

Share of voice normalises to 100% across the tracked category set. Baseline is the four weeks before the connector went live (14 Apr 2026). Month-to-date figures cover Aug 2026. 148.3k conversations in the selected window, +4.4% against the period before it.

Illustrative workspace. One real capture (Aug 2026); series are drawn.

Copeland & Ives is invented. The brands are real and none is a customer.

Live case studies

Three tabs we keep open. One operator who ran the playbook in-house, one brand answering inside the session, one public capture of what five models say from memory.

Tally · a form builder, 11 people, no outside funding

Tally built their own Beacon

They ran the whole playbook in-house, then published what it did.

Tally spent years being worth recommending first. The engineering keeps the answers current.What Tally ran for itself is the stack an agency runs for a book of clients.

What they built
  • The brain. An llms.txt, an AI info page written for the assistants to read, and twenty comparison pages shaped like answers.
  • The surfaces. A 21-tool MCP server, a ChatGPT app and a Claude connector, so Tally works inside the session.
  • The measurement. They track the prompts that surface them and their visibility against competitors, and they ask each new user which prompt found them.
  • #1acquisition channel is now AI search
  • 10,000+new users a week say an assistant sent them
  • 5xtracked ChatGPT sign-ups, overnight, this May
  • $422Kmonthly revenue, up from $258K ten months before
$258K
Ten months before
$422K
Latest reported

Crossed $5M a year on the way.

Monthly revenue, self-reported.

Self-reported figures, via Jake Ward's public breakdown, August 2026. Tally is a real company, unaffiliated with Beacon, and is not a customer. Read the public breakdown

Three real companies. None is a Beacon customer.

Every figure belongs to the source named on its tab.

The APIs and MCPs underneath that put this morning’s deal in this afternoon’s answers.

Beacon builds and runs the live feed, and captures what the assistants say back. A new deal, an ad campaign or a catalogue change is in the answers the day it ships.

New deal at nine, in the answers by ten

One live feed from your own catalogue, published over MCP and run by Beacon end to end. Put a deal, a campaign line or a price change into it and every client that speaks the protocol reads the same thing the same day.

  1. 01Deals and campaign lines land as you brief them
  2. 02Catalogue, stock and price update themselves from your systems
  3. 03Beacon does the engineering and the deployment

One source at the centre. Every client that speaks the protocol reads it.

See the answers move while the campaign runs

Beacon publishes the feed and captures what the assistants say back, so cause and effect sit in one place. Ship a campaign and the answers show its effect while the flight is still live.

  1. 01Every answer about you, captured as it changes
  2. 02A campaign’s outcome read straight from the answers
  3. 03Course-correct while it is still running

Your systems

PIM, ERP, BI

Beacon

MCP server, console

  • Into Beacon.

    • new deal
    • campaign line
    • catalogue
    • price
  • Back to you.

    • what the answer said
    • share of the answer
    • actions taken

changes in, what the answers said back out

What that does to the numbers

01

Reach your ICP

Your answer reaches the people already asking about your category, five times faster than a paid campaign finds them.

5x faster
02

Convert in the answer

CTAs built into the answer carry the shopper to your site and catalogue: find in store, add to cart, book.CTAs built into the answer carry every client’s shoppers to their sites and catalogues, under your name.

in the session
03

The weekly report

One file, against a baseline taken before the first surface went live.

weekly

Beacon builds and runs this layer. The marks above name the assistants the reporting covers. Each platform decides what it supports, and Beacon builds against those programmes as they open.

FAQs

What brands and agencies ask us before they start.

How is this different from a visibility dashboard?

There are two jobs here and Beacon does both. The reporting half is what a tracker does: which questions you appear in, what was said about you, how accurate it was, and where that sits against a baseline taken before you started. The building half is the branded answer itself, your catalogue and your steps running inside the assistant's reply, which is the work a dashboard leaves on your desk.

Is this GEO with a new name on it?

No, though they share a dashboard. GEO is about being included when a model writes its own answer, which is an earned job much like SEO was. Beacon builds the thing the assistant hands the person once your brand is in play: your catalogue, your steps, your actions, running inside the session. It reports on the earned side too, because both are measured on the same surface, but the two are different pieces of work with different owners.

How do you know what the assistants say about us?

We ask them. Your list of the questions buyers already put to an assistant is run on each one, and the answers are kept word for word, so a claim can be checked against the text that produced it. Method decides what a number means: an assistant answering from training memory with browsing switched off gives a different answer to the same assistant allowed to go and read the web, and the two are reported separately. One capture is a photograph, so a trend needs a second one.

How often do the numbers refresh?

Weekly. Every prompt on your list is re-run each week on the same wording, which is what makes this week comparable to last week. The baseline is taken before your first surface goes live, so the opening report has something to measure against.

Will an llms.txt file fix this?

No. Crawlers fetch it like any other text file, and no major AI search surface has been shown to prefer the sites that publish one. It takes minutes and does no harm, so publish it if you like; this site does. The movement comes from your own product pages: specifications, prices and availability, stated once and stated the same way in every market.

Do the platforms have to say yes?

For the flagship assistant surfaces, yes. Each one runs its own developer programme, and a surface is a build against that programme rather than a media buy against an auction. Underneath, the brain is published over MCP, so anything else that speaks the protocol, from Perplexity and Copilot to commerce apps like Shopee and Lazada, connects without another approval round. Beacon does the builds and keeps them current as the programmes move.

How long before anything is live?

One surface, one assistant, one market is weeks rather than quarters. The long pole is almost always catalogue readiness on your side rather than the connector on ours, because models are unforgiving about specifications that disagree with each other across markets. The Atlas exists so you can see the finished shape of it before anyone commits budget to it.

How would we know it worked?

Three numbers, and impressions is not one of them. Share of the answers in your category against a baseline taken before you started. Accuracy of what gets said about your products, measured against your own catalogue rather than against sentiment. And installed base, the count of assistants carrying your surface, which is an audience you do not re-buy every quarter. All three sit in the Console and all three export.

Where does the data actually go?

Beacon reads what you already publish, meaning catalogue, specifications and support content, and writes back only what your team has approved. Conversation content stays with the platform. What returns to you is aggregate: what was asked, what was answered, and what the answer was checked against. Nothing in the design requires building a profile of the person on the other side of the glass.

What happens when the platforms change the rules?

They will, and they already have more than once in the time these programmes have existed. That is the argument for the layer rather than against it: when a specification moves, the connector moves, and your catalogue, your approved answers and your reporting history carry across instead of being rebuilt. A layer nobody owns is a layer that quietly stops working.

We run this for clients. Does it work per client?

Agency monitoring is scoped by the prompts and sites being tracked. Confirm available assistant coverage, cadence, access and reporting in a walkthrough. Interactive assistant or plugin implementation for client brands is a separate custom service; its platform support, permissions and maintenance are agreed for each project.

What does it cost?

The pricing page lists SaaS monitoring scopes for prompt tracking, share of voice and basic AI visibility reporting. Enterprise and agency interactive assistant or plugin builds are custom-priced work outside those subscriptions. Request a scope that states the supported platforms, data access, delivery and maintenance responsibilities.

Priced by the prompts you track and the sites they cover.

A prompt is a question your buyers already put to an assistant, and SaaS monitoring reports where your brand stands in sampled answers.A prompt is a question your clients’ buyers already put to an assistant, and SaaS monitoring reports where each client stands in sampled answers.

SaaS monitoring covers prompt tracking, share of voice and basic AI visibility reporting. Confirm available surfaces, cadence and access in a walkthrough. Interactive plugin builds are scoped separately.

  • Starter

    $49/month

    For one site finding its feet in AI answers.

    • 25 prompts tracked
    • 1 site
    • Assistant coverage agreed in scope
    Talk to us
  • Pro

    $99/month

    For a brand that tracks its category seriously.

    • 50 prompts tracked
    • 5 sites
    • Assistant coverage agreed in scope
    Talk to us
  • Business

    $199/month

    For teams working across several markets at once.

    • 100 prompts tracked
    • 10 sites
    • Assistant coverage agreed in scope
    Talk to us
  • Agency monitoring

    $399/month

    For running client programmes under your own name.

    • 300 prompts tracked
    • Site coverage agreed in scope
    • Assistant coverage agreed in scope
    Talk to us
  • Enterprise and agencies

    Custom

    Interactive assistant and plugin implementation for enterprises and agencies is a separately scoped service, outside SaaS monitoring prices. We build for supported platforms such as ChatGPT and Claude; availability, permissions, integration work and maintenance are agreed for each project. Request a custom quote.

    Talk to us
Every plan in full detail

Launch list prices, in US dollars.

One email, straight to someone who builds these

Custom rollouts, agency programmes and questions about the plans all land in the same inbox.

Pick a time directly